LLM & Models
Project Glasswing: Claude Mythos Preview
Centered on Anthropic’s Project Glasswing and Claude Mythos Preview, this post explains why cybersecurity …
HYPERACCEL TECH BLOG
Chip design, memory, compilers, infrastructure, and models. HyperAccel engineers write down what they learn across every layer of the AI stack.
Click a layer to unfold its posts below
L5 · Model
Transformer internals, serving frameworks, and analyses of recent models.
LLM & Models
Centered on Anthropic’s Project Glasswing and Claude Mythos Preview, this post explains why cybersecurity …
LLM & Models
A hands-on walkthrough of Transformer-based LLM internals — from each module’s role to key optimization …
LLM & Models
Philosophy of SGLang Since the introduction of LLMs, they have been used to solve complex tasks in various …
L4 · Infra
How HyperAccel builds its infrastructure: Kubernetes dev environments, CI/CD, device plugins.
Infra & DevOpsK8s Dev Environment - Part 03
Hello! I’m Younghoon Jun, a DevOps Engineer on the ML team at HyperAccel. This post is the third installment …
Infra & DevOpsK8s Dev Environment - Part 02
The complete journey of redesigning HyperAccel’s CI/CD infrastructure based on Actions Runner Controller …
Infra & DevOpsK8s Dev Environment - Part 01
Hello! I’m Younghoon Jun, a DevOps Engineer on the ML team at HyperAccel. For those of you reading this, what …
L3 · Compiler
The software stack above the silicon: compiler theory, torch.compile, custom kernels, and Legato.
Compilers & KernelsExploring torch.compile() - Part 03
Where the industry is heading, as seen at PyTorch Conference 2026, through three keywords: Agent, …
Compilers & KernelsExploring torch.compile() - Part 02
Why is torch.compile split into Dynamo, AOTAutograd, and Inductor? Starting from how PyTorch grew its …
Compilers & KernelsMonads and Category Theory - Part 01
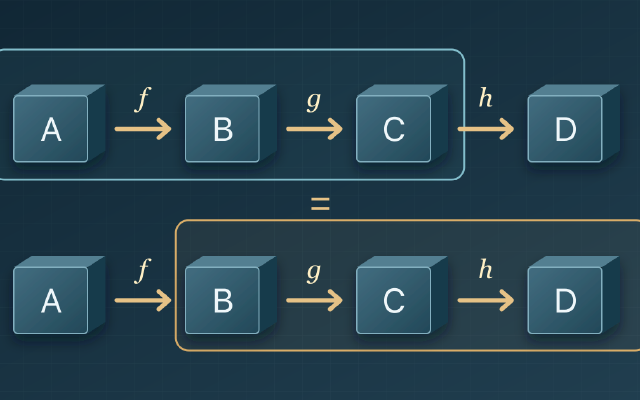
Starting with a type mismatch between functions that return Option, we explore how branching, map, join, and …
Compilers & KernelsExploring torch.compile() - Part 01
We take torch.compile apart into its three components — TorchDynamo, AOTAutograd, and TorchInductor — and walk …
Compilers & KernelsLegato - Part 01
An introduction to Legato — HyperAccel’s programming model and compiler stack for the LPU — covering what it …
Compilers & Kernels
An analysis of AITER (AI Tensor Engine for ROCm), which boosts inference performance on AMD GPUs.
Compilers & KernelsKnow Your Enemy - Extra
Learn about Pallas programming model that enables writing custom kernels on TPU.
Compilers & KernelsCrafting Compilers - Part 03
Today I brought a somewhat different topic. Have you ever thought it would be great if a compiler could …
Compilers & KernelsCrafting Compilers - Part 02
Before building a compiler, we need to define the language it will compile. A programming language isn’t just …
Compilers & KernelsCrafting Compilers - Part 01
Compilers This will be a series of posts describing what compilers are, how they are crafted, and how to build …
L2 · Memory
The memory hierarchy of the AI era: HBM, HBF, CXL, and KV-cache storage tiers.
Memory & StorageCeph Deep-Dive - Part 01
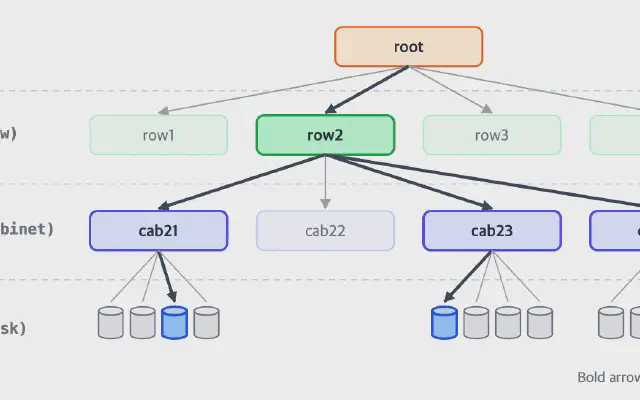
A walkthrough of CRUSH, the data distribution algorithm at the heart of Ceph, based on the SC'06 paper. It …
Memory & StorageMemory in the AI Era - Part 05
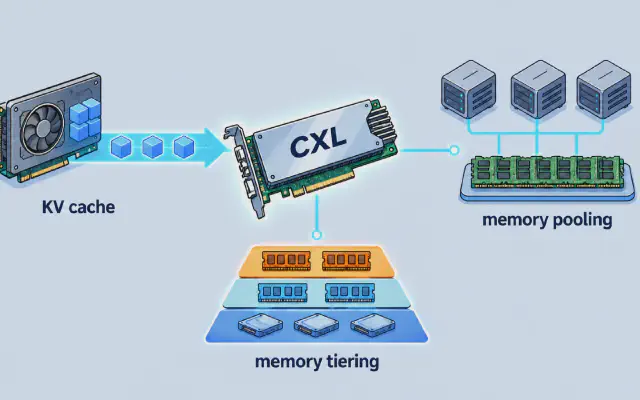
We examine how CXL is used in real workloads through KV cache offload, memory pooling, and memory tiering.
Memory & StorageMemory in the AI Era - Part 04
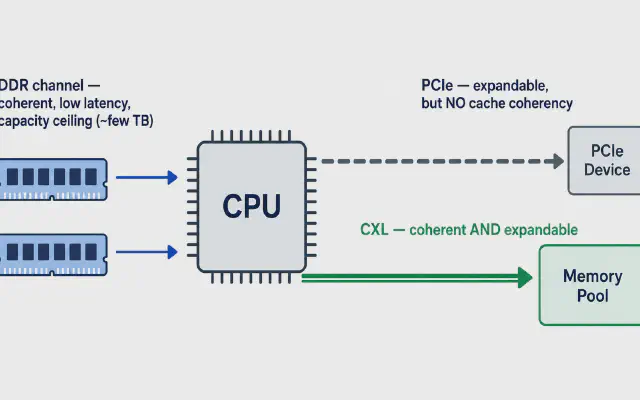
Next to the GPU, HBM and HBF fill the gap — but there’s another empty seat next to the CPU. We look at CXL, …
Memory & StorageMemory in the AI Era - Part 03
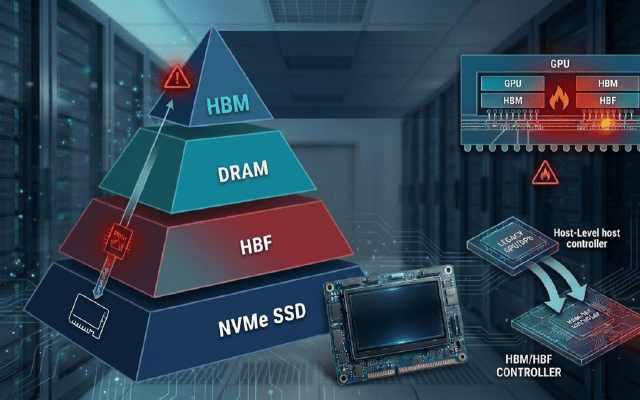
HBF clearly has its place, but it still has gaps to fill before it can claim a spot in the memory hierarchy …
Memory & StorageMemory in the AI Era - Part 02
Centered on SK hynix’s H³ architecture, we explore workloads that can overcome HBF’s weaknesses.
Memory & StorageMemory in the AI Era - Part 01
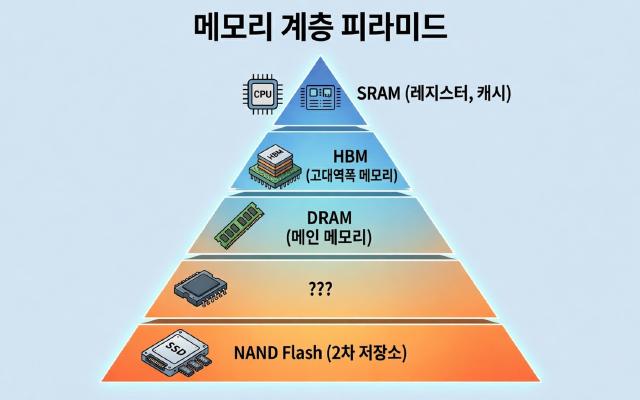
Why are there so many types of memory, and where does HBF fit in? From SRAM to HBF, we explore the physical …
Memory & StorageKnow Your Enemy - Part 04
We explore the technical principles behind NVIDIA’s ICMS — a new storage tier designed to solve the KV cache …
L1 · Hardware
Architecture deep dives on AI accelerators: GPU, TPU, LPU, wafer-scale chips, and CPUs.
AI Hardware
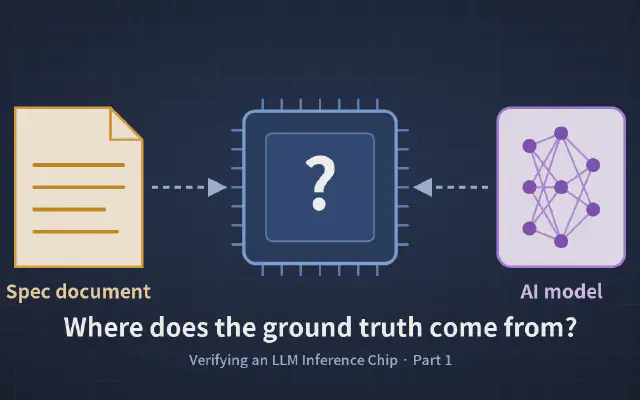
When the same AI model gives different answers on a GPU and on the LPU’s RTL, who is wrong? This post covers …
AI HardwareKnow Your Enemy - Part 07
The era of using AI to build chips that run AI has arrived. Drawing on publicly released information about …
AI HardwareKnow Your Enemy - Part 06
We analyze why the CPU became the bottleneck of inference infrastructure in Agentic AI workloads, walk through …
AI HardwareKnow Your Enemy - Part 05
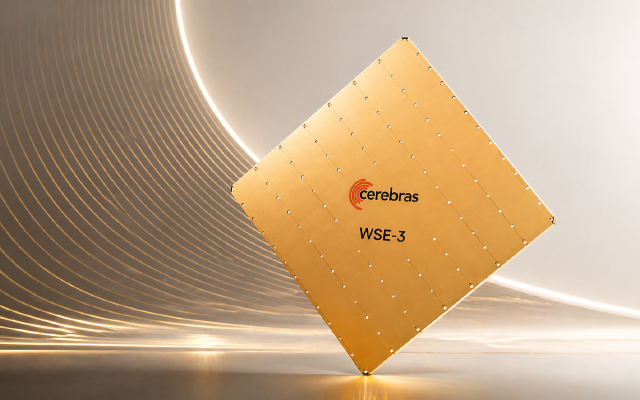
This post explains Cerebras’s recent momentum, WSE-3 architecture, and the trade-offs of wafer-scale chips in …
AI HardwareKnow Your Enemy - Part 03
We explore the background of Groq and LPU, their hardware/software design philosophy, and analyze NVIDIA’s …
AI HardwareKnow Your Enemy - Part 02
We explore the background of TPU’s emergence and analyze Google’s AI semiconductor strategy by examining its …
AI HardwareKnow Your Enemy - Part 01
An overview of how NVIDIA GPUs evolved and how the Hopper architecture hides memory latency with massive …
Compilers & KernelsExploring torch.compile() - Part 03
Where the industry is heading, as seen at PyTorch Conference 2026, through three keywords: Agent, …
Memory & StorageCeph Deep-Dive - Part 01
A walkthrough of CRUSH, the data distribution algorithm at the heart of Ceph, based on the SC'06 paper. It …
AI Hardware
When the same AI model gives different answers on a GPU and on the LPU’s RTL, who is wrong? This post covers …
Where the industry is heading, as seen at PyTorch Conference 2026, through three keywords: Agent, …
A walkthrough of CRUSH, the data distribution algorithm at the heart of Ceph, based on the SC'06 …
When the same AI model gives different answers on a GPU and on the LPU’s RTL, who is wrong? This …
Starting with a type mismatch between functions that return Option, we explore how branching, map, …
We take torch.compile apart into its three components — TorchDynamo, AOTAutograd, and TorchInductor …
An overview of how NVIDIA GPUs evolved and how the Hopper architecture hides memory latency with …
Why are there so many types of memory, and where does HBF fit in? From SRAM to HBF, we explore the …
An introduction to Legato — HyperAccel’s programming model and compiler stack for the LPU — covering …
Hello, my name is Taeseo Um, currently on the ML team at HyperAccel. There is a running joke among …
Hello! I’m Younghoon Jun, a DevOps Engineer on the ML team at HyperAccel. For those of you reading …
Compilers This will be a series of posts describing what compilers are, how they are crafted, and …
Architecture deep dives on AI accelerators: GPU, TPU, LPU, wafer-scale chips, and CPUs.
AI Hardware
AI HardwareKnow Your Enemy - Part 07
AI HardwareKnow Your Enemy - Part 06
AI HardwareKnow Your Enemy - Part 05
AI HardwareKnow Your Enemy - Part 03
AI HardwareKnow Your Enemy - Part 02
AI HardwareKnow Your Enemy - Part 01
The memory hierarchy of the AI era: HBM, HBF, CXL, and KV-cache storage tiers.
Memory & StorageCeph Deep-Dive - Part 01
Memory & StorageMemory in the AI Era - Part 05
Memory & StorageMemory in the AI Era - Part 04
Memory & StorageMemory in the AI Era - Part 03
Memory & StorageMemory in the AI Era - Part 02
Memory & StorageMemory in the AI Era - Part 01
Memory & StorageKnow Your Enemy - Part 04
The software stack above the silicon: compiler theory, torch.compile, custom kernels, and Legato.
Compilers & KernelsExploring torch.compile() - Part 03
Compilers & KernelsExploring torch.compile() - Part 02
Compilers & KernelsMonads and Category Theory - Part 01
Compilers & KernelsExploring torch.compile() - Part 01
Compilers & KernelsLegato - Part 01
Compilers & Kernels
Compilers & KernelsKnow Your Enemy - Extra
Compilers & KernelsCrafting Compilers - Part 03
Compilers & KernelsCrafting Compilers - Part 02
Compilers & KernelsCrafting Compilers - Part 01
Transformer internals, serving frameworks, and analyses of recent models.
LLM & Models
LLM & Models
LLM & Models
How HyperAccel builds its infrastructure: Kubernetes dev environments, CI/CD, device plugins.
Infra & DevOpsK8s Dev Environment - Part 03
Infra & DevOpsK8s Dev Environment - Part 02
Infra & DevOpsK8s Dev Environment - Part 01
How we work: AI coding agents, development methodologies, and running this tech blog.
Engineering CultureAI Agent - Part 02
Engineering CultureAI Agent - Part 01
Engineering Culture
Engineering Culture
Field reports from CES, NAVER DAN, PyTorch Conference, and more.
Conference Reports
Conference Reports
Conference Reports
Programming Language